
Image Scraper vs Save All Resources
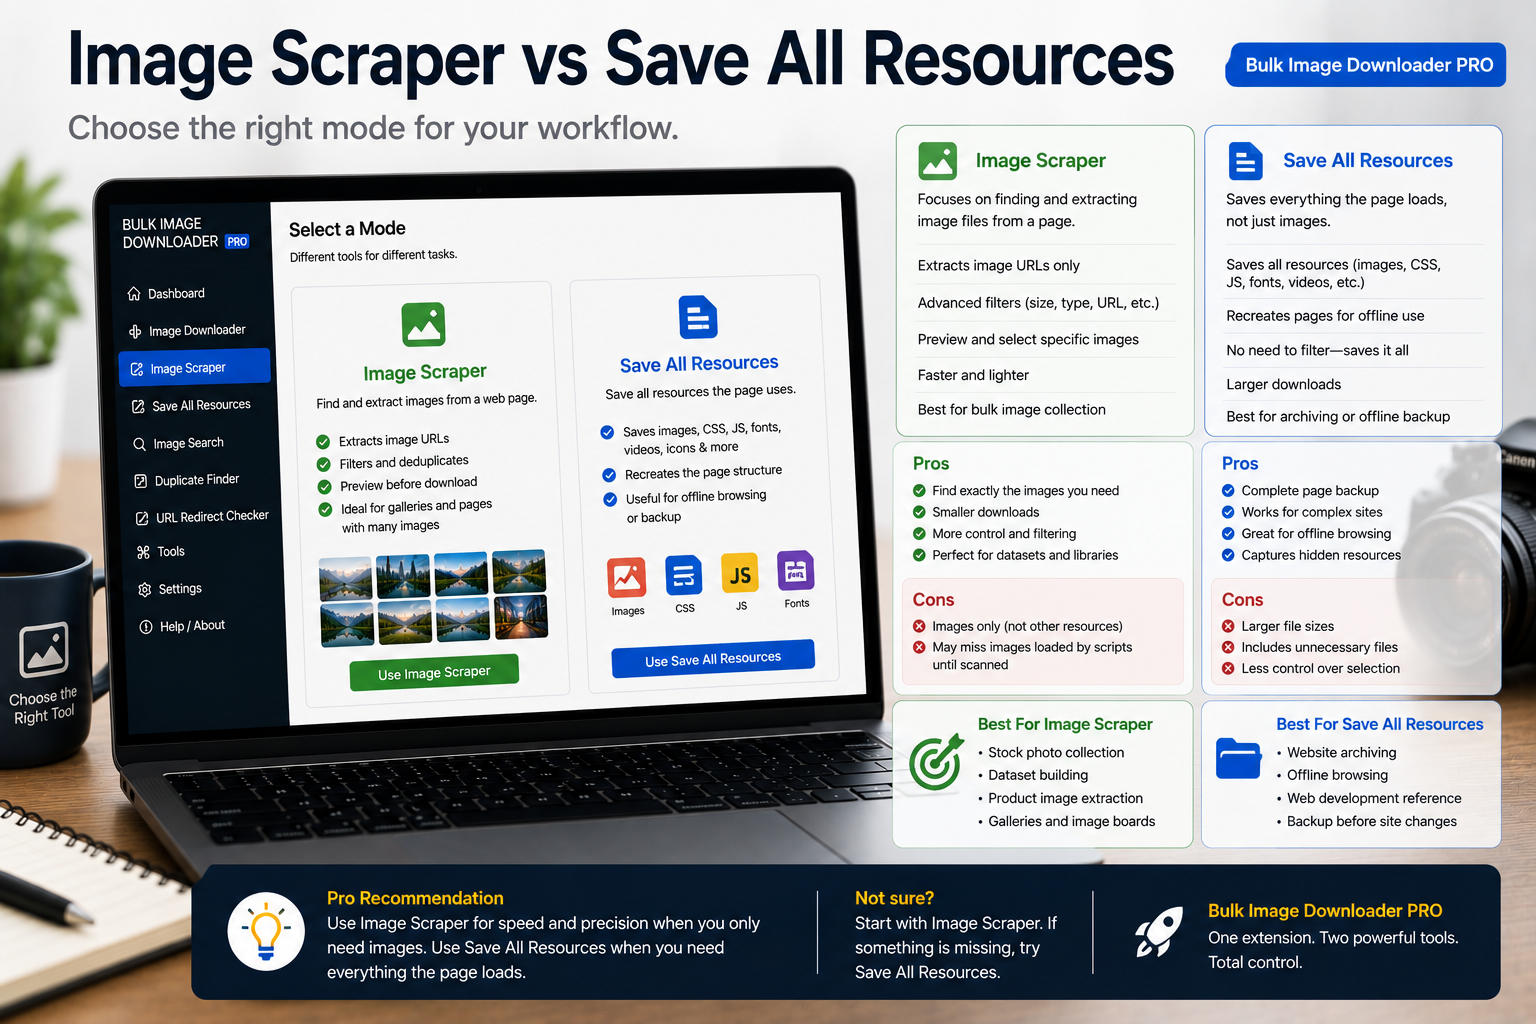
A front-end developer debugging a layout wants every CSS file, font, and script the page fetched. A merchandiser wants two hundred product photos, consistently named and sized. Those are different deliverables, and that is the core of image scraper vs Save All Resources.
Bulk Image Downloader From URL List is an image-focused scraper and download workflow tool. It is not a replacement for Save All Resources-style extensions that mirror a page’s full network activity.
What Save All Resources-style tools do
Extensions in this category export assets the browser already downloaded for a loaded page:- images, scripts, stylesheets, fonts, and other files
- often preserving folder structure from DevTools-style listings
- excellent for archiving one page or debugging what a site served
Limits of resource savers for image jobs
- anchored to one loaded page at a time
- cannot see images that never requested because scroll did not reach them
- no image dimension filters, filename templates, or visual deduplication
- no on-download resize, convert, or watermark workflow
What an image scraper optimizes for
Bulk Image Downloader From URL List finds and shapes pictures:- Deep Scan captures lazy-loaded and infinite-scroll images
- Bulk URL scrape processes many page URLs from a list
- side-panel filters for size, type, aspect ratio, and domain include/exclude
- Stack Mode merges multi-page results
- saved rules, sessions, and CSV export of scrape results
- options-page tasks with Download If URL rules, auto folders, and filename constructor
- on-download resize, convert (JPEG/WebP/PNG), optional EXIF strip, PNG watermark (PRO)
- perceptual duplicate finder after collection
Comparison at a glance
| Goal | Save All Resources style | Image scraper (this extension) |
|---|---|---|
| Export all page assets | Yes | No (images focused) |
| Crawl many page URLs | No | Yes |
| Lazy-load image capture | Limited | Deep Scan |
| Filter and rename images | No | Yes |
| On-download processing | No | Yes (PRO) |
| Visual duplicate removal | No | Yes |
Match the tool to the deliverable
Use a Save All Resources-style extension when you genuinely need every asset from one loaded page. Use an image scraper when the output is a curated photo set across pages, filtered and named for downstream use. Many teams keep both: resource savers for debugging, image scrapers for content production. Install it when pictures, not every network file, are the product.More alternatives are covered in best bulk image downloader extensions.
A resource saver keeps everything; a scraper can drop copies
Save All Resources-style tools are built to be indiscriminate, which is their strength and their cost. The extension can drop copies during the scan itself, before the set ever reaches a download. That single capability is most of the difference on a photo grid, where a resource saver collects every thumbnail, icon, and background asset on the page.
Because the drop happens at scan time, the list you carry forward is already smaller and its survivors are the ones worth naming. A resource saver hands you the network’s view of the page; a scraper lets you decide what from that view is actually the deliverable.
Continue reading: Image Downloader vs Bulk Media Downloader.