
Image Scraping vs Octoparse
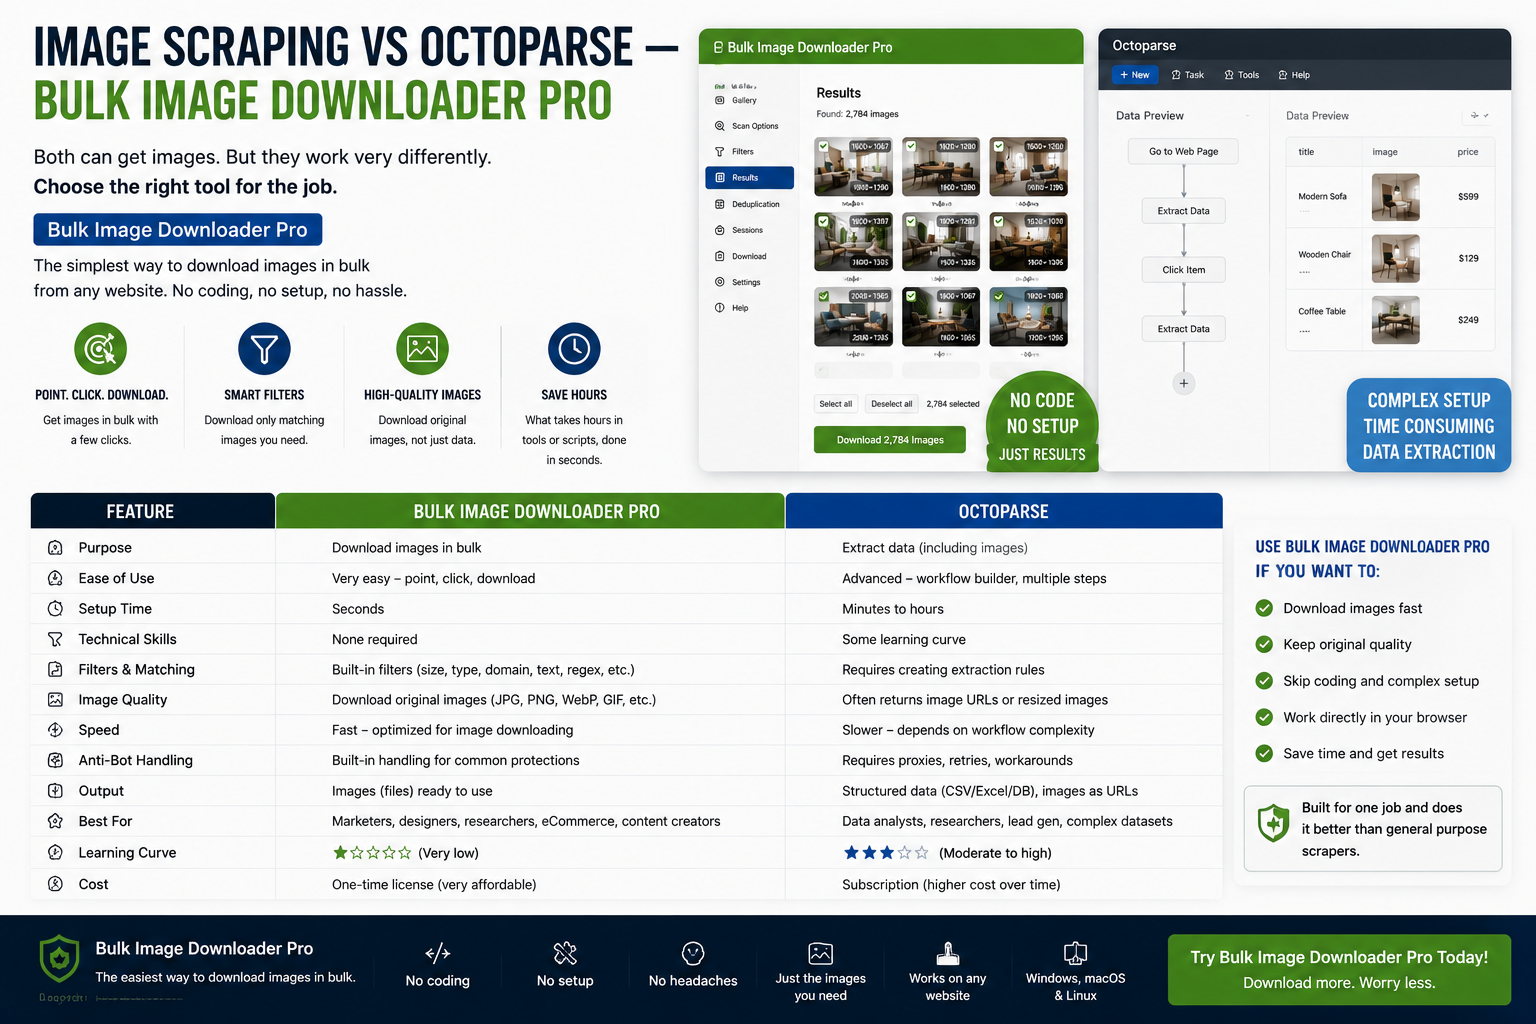
What Octoparse is built for
Octoparse targets general data extraction:- point-and-click field mapping on listing and detail pages
- pagination, loops, and workflow logic for large catalogs
- export to Excel, CSV, databases, or APIs on paid plans
- scheduled or cloud runs for recurring jobs (plan-dependent)
What a browser image extension adds for pictures
- Deep Scan, Area Scan, and Continuous Scanning for lazy-loaded galleries
- side-panel pagination (auto-detect or manual page ranges, up to 100 pages)
- Bulk URL scrape across pasted page URLs
- filters for dimensions, file type, aspect ratio, URL text, and domain include/exclude
- perceptual duplicate finder plus 404 and redirect checkers
- on-download resize or convert (JPEG/WebP/PNG), EXIF strip, PNG watermark (PRO; mutually exclusive per task)
- saved tasks, Download If rules, auto folders, and filename constructor tokens
Comparison table
| Need | Octoparse | Browser image extension |
|---|---|---|
| Multi-field structured datasets | Yes | No |
| Finished image files with filters | Secondary step | Yes |
| Visual no-code setup in browser | Desktop/cloud app | Yes (side panel) |
| Cloud scheduling at large scale | Yes (plans vary) | Queued tasks; Chrome must stay open |
| On-download image processing | No | Yes (PRO) |
| Visual duplicate detection | No | Yes |
Choose by deliverable
Pick Octoparse when the product is structured records across many fields and pages, and you accept workflow setup time. Pick Bulk Image Downloader From URL List when pictures are the product and you want capture, filtering, naming, dedupe, and processing in one browser workflow. Many teams use both: Octoparse for catalog data, an image extension when the handoff is visual assets rather than rows. Install the Chrome extension when images, not database columns, are what you ship.For more options, compare tools in our guide to best bulk image downloader extensions.
What each tool means by “the image”
Octoparse treats a picture as a field in a row, so the useful output is the record. The extension treats the picture as the deliverable, which is why two of its tools act on the images themselves before you save. Filter images lets you look through the pictures gathered from a download and keep or drop them, and Find duplicates groups pictures that look the same even when their links differ, so you can keep one and drop the copies.
Both open on top of Home rather than in a separate window, so the decision happens against the list you are about to save. If your final artifact is a set of clean image files, that pre-save pass is the part a row-oriented scraper does not give you.
Continue reading: Image Downloader vs Web Scraper IO.